Tevpro insights
How to Convert an SFCC Catalog Export Into Sanity NDJSON
Two practical paths for bringing Salesforce Commerce Cloud catalog data into Sanity: a Python XML-to-NDJSON import or Sanity Connect for ongoing synchronization.
Key takeaways
- Use a Python converter for a one-time migration, pilot, or controlled catalog refresh. You still need to define the Sanity schema and mapping rules yourself.
- Treat SFCC product IDs as stable identifiers. Import referenced categories before products, and keep SFCC-owned commerce data separate from editor-owned content.
- Use Sanity Connect when SFCC remains the live catalog source and products and categories need ongoing synchronization into Sanity.
- Validate the NDJSON and import into a non-production dataset first. Review IDs, references, locales, and overwrite behavior before a production run.
An SFCC catalog export can get products into Sanity quickly. It will not keep them current after the import. The right choice depends on whether you are moving a catalog once or keeping SFCC and Sanity connected over time.
There are two practical routes. Build a small Python converter for a controlled XML to NDJSON import, or use Sanity Connect for Salesforce Commerce Cloud when SFCC remains the live commerce system and Sanity needs a continuing feed.
Start with field ownership
Write down which system owns each field before you map XML. SFCC should normally own SKU, price, inventory, variants, and the product ID. Sanity can own product copy, campaign modules, buying guides, editorial media, and other merchandising fields that editors need to change without touching SFCC.
That boundary prevents a repeat import from erasing editorial work or turning Sanity into a second place to maintain price data.
Manual route: convert an SFCC export with Python
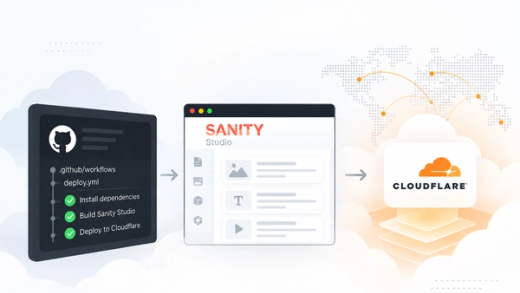
The manual route is plain by design. Export catalog XML from SFCC Business Manager, save it in an input folder, run a Python script, inspect the NDJSON output, and import it into a non-production Sanity dataset. Review a representative set of products in Studio before you use the same process against production.
The workflow
- Export the catalog XML from SFCC Business Manager.
- Save the source file with a date or release identifier so the import can be reproduced.
- Run the converter and write one Sanity document per NDJSON line.
- Validate IDs, expected document count, category references, variants, locales, and products that are no longer online.
- Import into a development or staging dataset, then inspect the result in Sanity Studio.
A simplified SFCC catalog export
Real exports vary by catalog configuration, locale, and custom attributes. This small example shows the fields the converter maps below.
<?xml version="1.0" encoding="UTF-8"?>
<catalog xmlns="http://www.demandware.com/xml/impex/catalog/2006-10-31"
         catalog-id="apparel-master">
  <product product-id="classic-blouse">
    <display-name xml:lang="en-US">Classic Blouse</display-name>
    <online-flag>true</online-flag>
    <custom-attributes>
      <custom-attribute attribute-id="longDescription">
        A lightweight blouse with a relaxed fit.
      </custom-attribute>
    </custom-attributes>
  </product>
</catalog>
The default SFCC namespace is why the Python example reads element names without their namespace prefix. Your export may include different custom attributes, multiple localized values, category assignments, images, and variant records.
Create the Sanity schema before mapping fields
The import cannot create a useful content model for you. Define every field you want to write, then keep SFCC owned data separate from editor managed fields. The examples below keep source IDs and commerce state read-only, while leaving room for editorial copy that later imports will not overwrite.
import {defineField, defineType} from 'sanity'

export const category = defineType({
  name: 'category',
  title: 'Category',
  type: 'document',
  fields: [
    defineField({name: 'sfccId', title: 'SFCC ID', type: 'string', readOnly: true}),
    defineField({name: 'title', type: 'string', validation: (rule) => rule.required()}),
    defineField({
      name: 'slug',
      type: 'slug',
      options: {source: 'title'},
      validation: (rule) => rule.required(),
    }),
    defineField({name: 'description', type: 'text', rows: 3}),
  ],
})
import {defineField, defineType} from 'sanity'

export const product = defineType({
  name: 'product',
  title: 'Product',
  type: 'document',
  fields: [
    defineField({name: 'sfccId', title: 'SFCC ID', type: 'string', readOnly: true}),
    defineField({name: 'title', type: 'string', validation: (rule) => rule.required()}),
    defineField({
      name: 'slug',
      type: 'slug',
      options: {source: 'title'},
      validation: (rule) => rule.required(),
    }),
    defineField({name: 'description', type: 'text', rows: 4}),
    defineField({
      name: 'categories',
      type: 'array',
      of: [{type: 'reference', to: [{type: 'category'}]}],
    }),
    defineField({
      name: 'commerce',
      type: 'object',
      fields: [
        defineField({name: 'online', type: 'boolean', readOnly: true}),
      ],
    }),
    defineField({
      name: 'editorial',
      title: 'Editor-managed content',
      type: 'object',
      fields: [
        defineField({name: 'buyingGuideCopy', type: 'array', of: [{type: 'block'}]}),
      ],
    }),
  ],
})
Import category documents before products if products reference categories. The stable IDs in both examples make that order predictable: category.womens-tops exists before product.classic-blouse points to it.
The converter below reads the simplified export, ignores the XML namespace, maps a custom attribute, and writes product documents with stable IDs:
from pathlib import Path
import json
import re
import xml.etree.ElementTree as ET

SOURCE = Path("catalog.xml")
OUTPUT = Path("catalog.ndjson")


def tag_name(element: ET.Element) -> str:
    return element.tag.rsplit("}", 1)[-1]


def direct_text(element: ET.Element, name: str, fallback: str = "") -> str:
    for child in element:
        if tag_name(child) == name:
            return (child.text or fallback).strip()
    return fallback


def custom_attribute(product: ET.Element, attribute_id: str) -> str:
    for element in product.iter():
        if (
            tag_name(element) == "custom-attribute"
            and element.attrib.get("attribute-id") == attribute_id
        ):
            return (element.text or "").strip()
    return ""


def slugify(value: str) -> str:
    return re.sub(r"[^a-z0-9]+", "-", value.lower()).strip("-")


root = ET.parse(SOURCE).getroot()
records = []

for product in root.iter():
    if tag_name(product) != "product":
        continue

    sfcc_id = product.attrib["product-id"]
    title = direct_text(product, "display-name", sfcc_id)
    description = custom_attribute(product, "longDescription")
    online = direct_text(product, "online-flag").lower() == "true"

    records.append(
        {
            "_id": f"product.{sfcc_id}",
            "_type": "product",
            "sfccId": sfcc_id,
            "title": title,
            "slug": {"_type": "slug", "current": slugify(title)},
            "description": description,
            "commerce": {"online": online},
        }
    )

with OUTPUT.open("w", encoding="utf-8") as ndjson:
    for record in records:
        ndjson.write(json.dumps(record, ensure_ascii=False) + "\n")

print(f"Wrote {len(records)} documents to {OUTPUT}")
The output is NDJSON, not one large JSON array. Every line is a standalone Sanity document. This example emits the category first, then a product with a valid category reference:
{"_id":"category.womens-tops","_type":"category","sfccId":"womens-tops","title":"Women's Tops","slug":{"_type":"slug","current":"womens-tops"}}
{"_id":"product.classic-blouse","_type":"product","sfccId":"classic-blouse","title":"Classic Blouse","slug":{"_type":"slug","current":"classic-blouse"},"description":"A lightweight blouse with a relaxed fit.","categories":[{"_type":"reference","_ref":"category.womens-tops"}],"commerce":{"online":true}}
Import the NDJSON into Sanity
After validating the file, import it into a non production Sanity dataset first. Sanity’s import tool accepts NDJSON files, with one document per line. Run the command from a project configured for the target Sanity project and use the dataset name you actually intend to populate.
# Import the reviewed NDJSON into a non-production dataset
npx sanity@latest datasets import output/catalog.ndjson staging
Sanity will reject an incoming document when the same ID already exists unless you intentionally choose an overwrite option. Treat a repeat import as a separate review step: back up the target, confirm field ownership, and verify that the run will not replace editor-managed content.
The part that takes time is the mapping. You need to create every Sanity schema field you intend to import. If SFCC has a material attribute, a product badge, a localized description, or a category relationship that matters on the site, define the field in Sanity first and add the matching transformation rule to the script.
Do not blindly import every SFCC attribute because it exists. Start with fields the storefront or editors will use. Add the rest after the first import proves the shape is right.
What to validate before importing
- Stable IDs. Use the SFCC product ID in the Sanity ID or store it as a permanent external ID. A title is not stable enough.
- References. Categories, master products, variants, and related products need valid Sanity references or a deliberate alternative.
- Locales. Map SFCC locales to the same locale strategy used by the Studio and storefront.
- Repeat imports. Decide which fields the script can patch and which editorial fields it must leave alone.
- Images. Decide whether to retain SFCC image URLs, upload assets to Sanity, or keep campaign imagery in a separate editorial workflow.
The manual route works well for a one-time migration, a small catalog, or a pilot. It becomes harder to operate when catalog changes need to move continuously, variant updates are frequent, or many locales need to remain in sync.
Continuous route: Sanity Connect for SFCC
Sanity Connect is Sanity's SFCC integration. It includes the int_sanity_connect cartridge for Salesforce B2C Commerce, the @sanity/sfcc Studio plugin, and storefront integration patterns.
The cartridge uses the SFCC Jobs framework for an initial full catalog sync and later delta syncs. Products and categories become Sanity documents, with read-only commerce fields beside editor controlled fields for enrichment.
This route makes sense when SFCC stays authoritative and the business needs Sanity to receive ongoing product and category changes. The cartridge handles much of the integration plumbing, but the team still needs to define editorial fields, set up locales, decide how the storefront combines commerce data with Sanity content, and test failures and re-syncs in a sandbox.
Sanity's full sync creates documents for products, variants, and categories. Estimate catalog and variant volume before production, because those documents count against the Sanity plan.
Which route should you use?
Use Python when you need to migrate a catalog, validate a new content model, or run a controlled bulk refresh. It is fast to build, easy to inspect, and gives the team a chance to learn the source data before committing to an ongoing integration.
Use Sanity Connect when SFCC is the live source of truth and content needs to stay current in Sanity. It is the better fit for continuous synchronization, provided the team is ready to own the setup and operating model.
Start with 25 to 50 products that include variants, categories, images, localized fields, and at least one discontinued item. That test will expose the mapping decisions that a full catalog import tends to hide.
Sources
Why work with us
Why Tevpro?
Whether you’re a startup with a bold product idea or an established company seeking a stronger delivery partner, Tevpro delivers results. Our expert consultants specialize in building secure, scalable applications that simplify operations and drive real ROI.
FAQ
SFCC to Sanity import questions
These decisions usually determine whether the first import becomes a reusable process or a cleanup project.
No. Sanity imports JSON or NDJSON documents, so the XML needs to be transformed first. A Python script can parse the XML and write one valid Sanity document per line.
Commerce integration planning
Need a catalog migration path your team can operate?
Share your SFCC catalog, storefront, and content-model constraints. We will help frame a practical import or integration path.