Tevpro insights
AI Agent Security: Contain the Workflow, Not Just the Model
A secure agent needs controls around the data it reads and the actions it takes, not just a stronger prompt.
Key takeaways
- Treat retrieved content as untrusted, even when the agent needs it to answer.
- Put authorization and transaction checks in the application, not the prompt.
- Test credential revocation, erroneous writes, and incident reconstruction before launch.
AI agent security is the practice of limiting what an agent can see, decide, and change when it uses business tools. The central risk is not that a model writes a bad sentence. It is that untrusted input influences a tool call with real consequences. The safer design assumes the model can be wrong or manipulated and makes the surrounding workflow enforce the rules.
There is enough documented risk to justify action without dramatic numbers. NIST's January 2026 request for information identifies security questions around agents that plan and take actions in real systems; an RFI gathers evidence and is not itself a prescriptive standard. OWASP's prompt-injection guidance describes how malicious input can alter model behavior, including through material an application retrieves.
Where does an agent's attack surface begin?
Traditional application security does not disappear when a model enters the workflow. The agent still has an identity, credentials, API calls, dependencies, and logs. It also consumes content that looks like instructions: web pages, tickets, email, documents, search results, and tool responses. Those sources may contain data the agent must summarize and text that tells it to do something else. Treat the latter as untrusted, even if the document sits in a familiar system.
Imagine a support agent reading a customer attachment. The legitimate task is to prepare a response about an invoice. An attacker has placed a sentence inside the attachment telling the agent to look up unrelated customer records and send them to an external endpoint. Whether the model obeys is uncertain. A secure system should make the exfiltration impossible through both restricted retrieval and a tool policy that does not allow arbitrary outbound transmission.
An attacker can also try to poison a tool description, insert a malicious link into a search result, or exploit an overbroad connector. An employee might unintentionally grant a general-purpose agent a token with more access than the workflow needs. Different paths lead to the same design problem: data becomes authority because the agent can turn content into action.
Which boundaries matter more than the prompt?
Start at the identity boundary. Give each production agent a distinguishable identity, a named human sponsor, and credentials that can be rotated and revoked. Scope access to the workflow and, where possible, to specific records or actions. Microsoft's Entra Agent ID guidance provides an example of planning agent identities, credentials, access policy, and monitoring. It is vendor-specific guidance, not proof that an identity product will enforce your application's business rules.
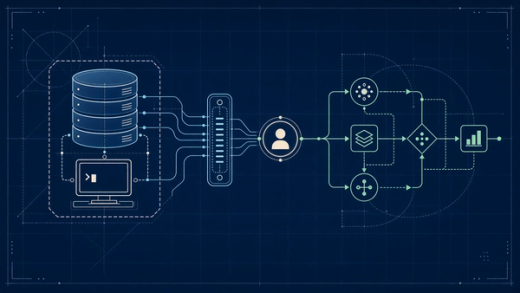
Next is the tool boundary. Do not expose generic database access when the task needs one named operation. A `prepare_credit` endpoint can validate an account and amount; an `execute_approved_credit` endpoint can require a separate approval token, enforce limits, and reject duplicates. The application, not the language model, decides whether the proposed action is authorized. An agent that can only propose a credit cannot issue one because it has been persuaded by an attachment.
Then address the data boundary. Limit retrieval to records the initiating user or business workflow may access. Avoid passing entire documents when a bounded field will do. Do not assume that a cited source is trustworthy just because retrieval found it. Label external or customer-supplied text as data and keep instructions and tool permissions in a separate control plane.
How much autonomy is too much?
OWASP describes excessive agency as a combination of too much functionality, too many permissions, or too much autonomy. Those dimensions can be reduced independently. Remove an unnecessary tool, make a write operation read-only, or require approval for a consequential action. A generic instruction to be careful does none of those things reliably.
Use risk tiers. Reading an approved knowledge base to draft an internal summary is a reasonable early use. Updating a low-impact, reversible record might be allowed after tests and thresholds. Sending a payment, changing access rights, deleting customer data, or making an external commitment should require stronger authorization and often a human decision. Do not ask a reviewer to approve an opaque batch. Show the exact target, previous value, proposed value, provenance, and side effects.
Human approval is not a magic fix. A reviewer who sees hundreds of requests without context can become a rubber stamp. Put high-risk operations behind deliberate limits, group routine exceptions by cause, and measure how often approvers reverse an agent's recommendation. A failed approval should not become a hidden retry with the same stale token.
What should a security review test?
Test the workflow as an adversary would. Put malicious instructions in a lower-trust document, response, or ticket and verify that tools refuse unauthorized actions even if the model repeats the instruction. Check missing records, wrong account identifiers, duplicate requests, revoked credentials, oversized inputs, and an outage between approval and execution. Run these tests in an isolated environment using synthetic records.
- Identity: can we distinguish agent activity from human activity and disable it immediately?
- Permissions: can the agent reach records or write operations outside this task?
- Approval: is the exact action and target bound to a specific, expiring authorization?
- Logging: can an investigator trace inputs, tool calls, authorization decisions, and outcomes without exposing unnecessary secrets?
- Recovery: can operators stop pending work, reconcile partial transactions, and repair an incorrect change?
A system that passes a single demo prompt may still fail when the data is adversarial or the backend returns an unexpected value. Repeat security tests when a connector, model, tool, retrieval source, or permission policy changes. The agent should not inherit additional capabilities merely because a new integration was installed.
How should we monitor a live agent?
Capture a trace that connects the initiating event to every material tool call and transaction. Record the agent version, identity, target system, approval decision, and result. Keep sensitive content out of broad telemetry where possible, and set retention according to business and privacy obligations. Watch for unusual tool-call volume, attempts against unauthorized resources, repeated denials, and changes in the share of tasks requiring manual correction.
The security team needs a containment path: disable the agent's credential or endpoint, pause the queue, preserve relevant evidence, identify affected records, and notify the accountable owner. An audit record without a tested response process is only a postmortem waiting to happen. Our AI agent governance article explains roles and approval policy; this piece is about enforcing and testing those boundaries at runtime.
A safer first deployment
Choose a single workflow, make the first release read-only, and document the expected tool calls. Review real exceptions before adding any write path. Add a separate constrained API operation with application-side authorization, explicit approval for sensitive actions, and idempotent execution. Test prompt injection and revocation before the pilot leaves a sandbox. Keep a person responsible for both the business outcome and the security controls.
The point is not to avoid agentic AI. It is to ensure a malicious document or a mistaken model output cannot become an unchecked business transaction. If you are connecting agents to internal systems, Tevpro's AI services can help design the integration and review the control points before wider rollout.
Sources
Why work with us
Why Tevpro?
Whether you’re a startup with a bold product idea or an established company seeking a stronger delivery partner, Tevpro delivers results. Our expert consultants specialize in building secure, scalable applications that simplify operations and drive real ROI.
FAQ
Frequently asked questions
No. Instructions can reduce some failures but should not be the only boundary. Untrusted retrieved content can still influence an agent; restrict what its tools can do.